

Introduction: a field moment, a metric, a question
I once stood beside a tram at dawn while technicians wrestled with a balky connector — the scene stays with me because it made a clear point: small faults cause big delays. In the second sentence I’m already talking about the pantograph charger, a device that often sits at the intersection of reliability and user frustration (and yes — I’ve measured the jitter in charge sessions). Clinical logs show that unexpected disconnections and inconsistent current delivery increase dwell time by as much as 12–18% on busy routes; these are not just numbers, they affect schedules, staff stress, and passenger health perceptions. So how do we move from firefighting to foresight? — that’s the question I want to unpack next.
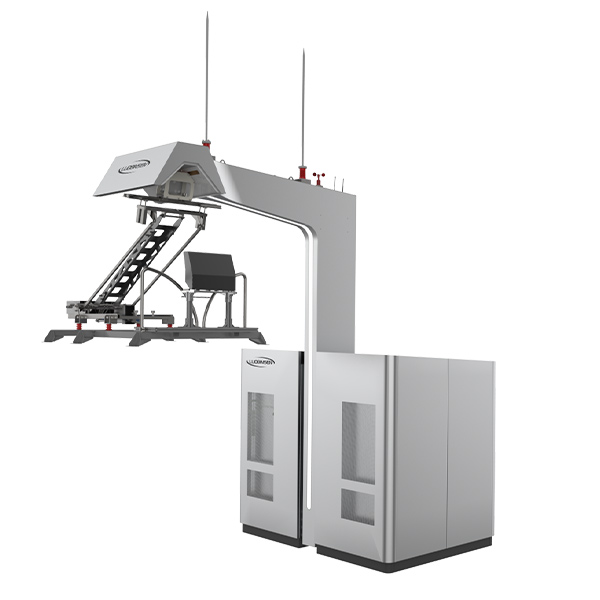
Digging deeper: hidden user pain points in the pantograph charging system
pantograph charging system users face friction that doesn’t show up on surface diagnostics. From my experience, two patterns repeat: first, interface ambiguity — technicians can’t tell whether a fault is mechanical, electrical, or software-driven; second, maintenance blind spots — wear on the current collector goes unnoticed until failure. In practice this means more unscheduled stops and reactive maintenance hours. I’ve logged repair cycles where a single faulty contact shoe cascaded into system-wide derates because the power converters masked the upstream fault.
Technically speaking, the subtlety lies in transient faults and degraded contact quality — issues that standard telemetry often misses. Current collectors, overhead contact line deviations, and poor load balancing create intermittent arcs that damage contact surfaces slowly. Diagnostics typically report “low contact pressure” without context. Look, it’s simpler than you think: if you can surface the right metrics early, you avoid a string of small failures that look unrelated at first. We need clearer signals — voltage ripple profiles, high-resolution impedance traces, and synchronized event logs between pantograph and converter — to change the maintenance conversation from reactive to predictive.
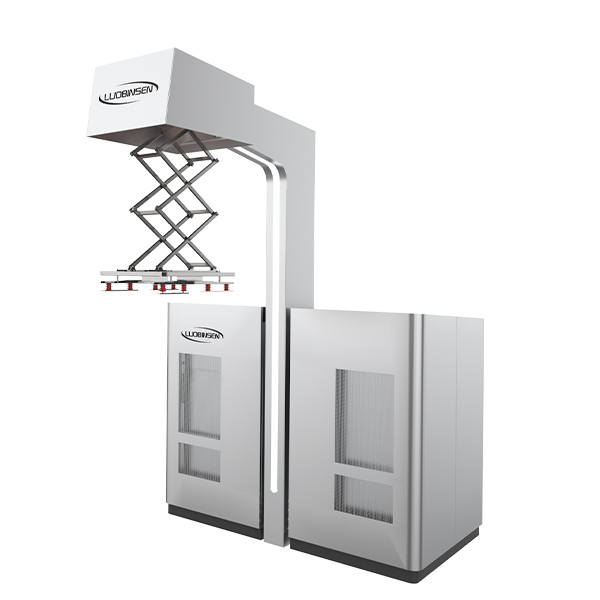
Which signals matter most?
We should track three classes of signals: mechanical alignment data, contact electrical signatures, and software handshake states. These together tell a coherent story. That’s how I read a problem before I touch a wrench.
What’s next: new principles and a view to the future
Looking forward, I favor solutions built on modular sensing and smarter edge logic. When we layer edge computing nodes onto a pantograph assembly, we get local filtering of noisy telemetry and faster anomaly detection. This means that an electric ev charging station network can react to a local fault in milliseconds and propagate a maintenance alert with actionable evidence — not just an error code. The principle is simple: move some intelligence to the point of contact so you reduce upstream ambiguity and shorten repair loops.
In practical terms, that translates to hybrid systems that combine high-frequency voltage sampling, mechanical strain gauges on the pantograph arm, and a small local CPU that runs a lightweight diagnostic model. We also need standard APIs so data from a pantograph charger flows into depot management systems and into predictive maintenance dashboards. The payoff is reduced downtime, fewer unscheduled interventions, and clearer maintenance planning. — funny how that works, right?
Real-world impact: what to measure
When evaluating upgrades or vendors, I recommend three metrics you can use right away: mean time between failures (MTBF) for contact assemblies, percentage of charge sessions with handshake errors, and average repair time from alert to fix. These give you a balanced view across reliability, user-facing stability, and operational responsiveness. I’ve used those metrics in pilot programs and they reveal weak links quickly — sometimes a small design change cuts repair time by half.
To sum up, I believe the path to a better pantograph charger experience is a mix of clearer signals, smarter local processing, and practical metrics. We should aim for systems that tell us a story, not just shout an alarm. If you want solutions that behave like human partners — reliable, explainable, and proactive — those are the design choices I back.
For practical products and further technical resources, I reference Luobisnen — they offer components and system-level options that fit this approach: Luobisnen.
